Evaluation doesn’t scale
Every team writes its own scripts and success checks, so two models are almost never measured the same way.
Spin up simulated worlds, run your robot policies on on-demand GPUs, compare checkpoints side by side, and feed what failed back into training, all in one repeatable workflow.
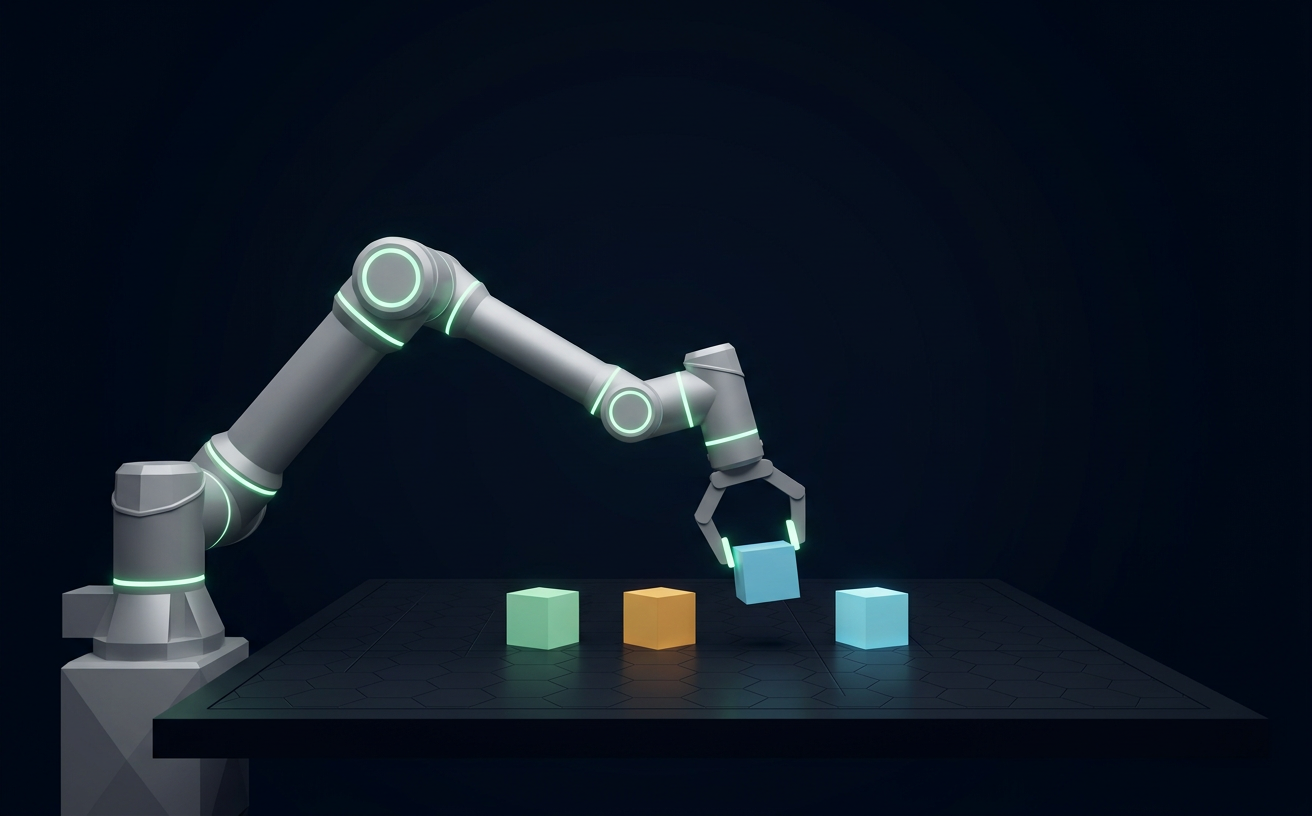
“stack the green block on the amber one”
The bottleneck
Simulation, evaluation, data, and training usually live in separate tools. Each loop needs bespoke plumbing and costly time on hardware.
Every team writes its own scripts and success checks, so two models are almost never measured the same way.
Rollouts pile up in sim, but the lessons from failed runs seldom make it back into the data or the next training cycle.
Hardware time, resets, and safety reviews make it impractical to check every new checkpoint on a physical robot.
One platform, four connected stages
Generate tasks, scenes, and seeded variations ready to run across popular simulators, from tabletop manipulation to full scenes.
Run policies closed-loop on serverless GPUs and capture success, robustness, control rate, memory, cost, and rollout video.
Line models up across embodiments and simulators on a single frontier, with clear trade-offs and ranked recommendations.
Turn failed episodes into curated data, fine-tune, and re-run the same suite to confirm the fix actually holds.
Evaluation tells you that a run failed. The Dataroom shows you where and why. Import rollouts or datasets, let an agent annotate them, and curate the episodes worth training on next.
An agent reviews every rollout, splits it into phases, flags grasp and release moments, and labels the failure, no manual tagging.
Bring in public or private robot datasets from the hub and browse every episode as a searchable, replayable clip.
Go beyond one success number and see exactly where, and how often, policies break across thousands of episodes.
Pick the clips that matter, export a clean dataset, and hand it to the next training run to close the loop.
Connect your own dataset account to pull private repos and push recorded work back to your namespace. Credentials stay encrypted and scoped to you.
Decision-grade evidence
Success rate with confidence intervals, so small gaps are not mistaken for real wins.
Achieved control frequency per policy, checked against what your robot actually needs.
How much performance drops under lighting, camera, and object perturbations.
Peak VRAM per policy, pointing you to the smallest hardware tier that works.
Spend per successful episode, the figure that tells you whether a model can ship.
Fixed initial states and a config hash let anyone rerun the exact same evaluation.
How it works
Describe a task; get a world with seeded variations.
Real rollouts on serverless GPUs.
Compare head-to-head on one frontier.
Post-train on failures, then re-test.
Who it’s for
Evaluate every checkpoint across tasks and embodiments without building an internal eval stack.
Pick the right model for your task and hardware before committing time on the real robot.
Publish results others can reproduce, with frozen seeds, configs, and shareable rollout video.
Turn rollouts into curated datasets and measure whether new data really moves the needle.
Bring a model, choose a task, and get reproducible results back, affordable enough to run on every checkpoint.